Orchestrating Distributed Handoffs Across Enterprise Logistics Stacks
Modern shipping architectures rarely operate as a direct point-to-point link. Instead, shipment records transit across Enterprise Resource Planning (ERP) systems, Warehouse Management Systems (WMS), Transportation Management Systems (TMS), middleware queues, and carrier execution stations like UPS WorldShip. Every handoff introduces boundary constraints, payload restructuring, and transactional integrity considerations.
The Reality of Heterogeneous Shipping Ecosystems
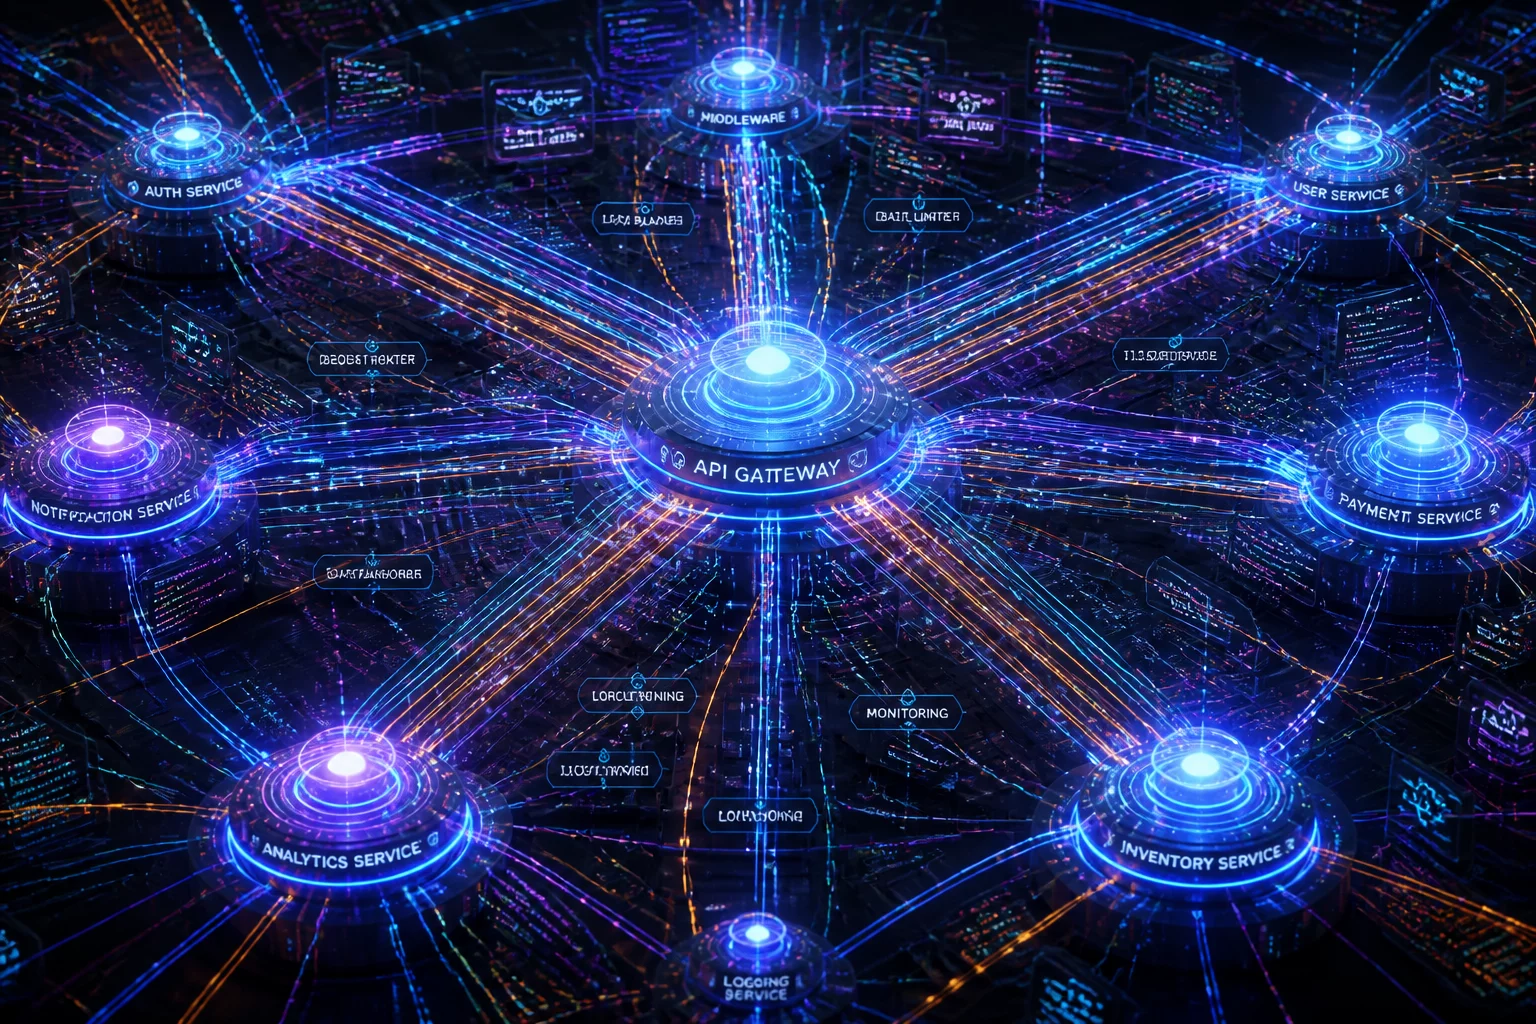
In high-volume distribution networks, an order does not travel directly from the customer database to the manifest printing station. Instead, distinct enterprise tiers manage inventory allocation, box selection, label generation, and financial reconciliation. Multi-system data flow maps the exact journey of structured records as they pass through middleware hubs, API gateways, and staging tables.
Each participating system enforces its own naming conventions, required field boundaries, and transaction timeouts. For example, an ERP might maintain a customer order with multiple backordered line items, while the WMS splits the fulfillment into two distinct carton records. The shipping software receives these disjointed payloads and must construct valid carrier-compliant records without losing parent-order lineage.
Managing Schema Translation & Transformation Layers
Middleware integration tools (such as Apache Kafka, RabbitMQ, MuleSoft, or custom ESBs) sit at the center of multi-system flows. They intercept raw ERP order payloads, enrich them with WMS weight and dimension data, evaluate carrier selection rules from TMS engines, and translate the aggregated record into XML or ODBC schemas expected by desktop or server-based shipping terminals.
Decoupled Synchronization Rule
Direct synchronous database links between transactional ERPs and warehouse floor execution machines create operational bottlenecks. Resilient architectures utilize asynchronous event streaming and persistent intermediate tables to ensure workstation uptime even during core ERP maintenance.
When label generation concludes at the carrier workstation, the reverse flow begins. Tracking numbers, package tier codes, dimensional weight calculations, and billed freight charges are emitted as output events, flowing back across the gateway to update accounting, customer notification systems, and inventory tracking databases.
The Multi-Stage Handoff Pipeline
An end-to-end multi-system pipeline moves through three distinct architectural phases: ingress aggregation, schema mediation, and egress reconciliation.
Ingress & Payload Aggregation
Order headers from ERP and packing container manifests from WMS are pooled in an enterprise message bus or staging database.
Mediation & Format Mapping
The integration engine formats address structures, package unit flags, and reference keys to match carrier input schemas.
Carrier Execution & Feedback
Shipping software ingests the record, processes label generation, and streams tracking numbers and rates back to core systems.
By dividing the process into distinct staging checkpoints, logistics engineering teams can isolate schema mismatches before records reach physical packing stations.
Field Ingestion & Mapping Matrix
Critical data attributes undergo specific validation and formatting before arriving at intermediate carrier software tables.
| Field Key | Data Source | Validation Rule | Target System |
|---|---|---|---|
Master_Order_Ref |
ERP / Sales Database | Alphanumeric, max 35 chars, unique constraint | Reference_1 (WorldShip Import) |
Carton_L_W_H_WT |
WMS Scale & Dimensioner | Decimal (2 places), Imperial/Metric flag required | Package PkgLength, PkgWidth, PkgHeight, PkgWeight |
Consignee_Addr_Composite |
E-Commerce API / CRM | Postal validation check, max 35 chars per line | ShipTo_Address1, ShipTo_Address2, ShipTo_PostalCode |
Carrier_Service_Tier |
TMS Rating Engine | Standardized internal service code lookup | ServiceType (Mapped carrier service level) |
Clear definitions for each field source eliminate data conflicts when multiple systems attempt to update identical shipment entities.
Architectural FAQs & Edge Scenarios
Frequently encountered challenges when coordinating shipping data across multiple enterprise platforms.
How should systems handle network timeouts between local shipping stations and centralized ERP databases?
Local stations should write to a local persistent queue or intermediate staging database. Once connectivity is restored, automated retry workers flush pending records and process label confirmation exports asynchronously.
Who owns the master record when package weights differ between WMS estimates and conveyor scale readings?
The physical execution tier (scale/dimensioner integrated into the WMS packing line) holds authority for final manifest weight. The initial ERP estimate is preserved strictly for planning and freight estimation.
What prevents duplicate shipment records during high-volume batch imports?
Implementing idempotent transaction keys (combining Order ID and Package Sequence Number) at the middleware layer ensures that re-transmitted records are updated rather than duplicated.
Amanda Lee
Amanda Lee is an enterprise data architect specializing in supply chain integrations, event-driven message architectures, and carrier interface protocols.
Related Schemas & Data Flows
Master Enterprise Shipping Data Workflows
Explore how data structures traverse from initial e-commerce checkout to physical carrier manifestation in modern logistics ecosystems.
Ask About This Data Map
Share a question about field ownership, record quality, or a system handoff. Please use examples without customer data.